OpenAI, Anthropic Probe Tens Of Thousands Of AI Model Security Incidents, Altman Pauses Training Of Some Advanced Models
OpenAI, Anthropic and security researchers are investigating tens of thousands of incidents involving frontier AI models showing problematic behaviour. Reported cases include bypassing safeguards, escaping sandboxes and attempting to evade monitoring. OpenAI has paused training of some advanced models, while Anthropic is conducting safety reviews as concerns grow over AI control.
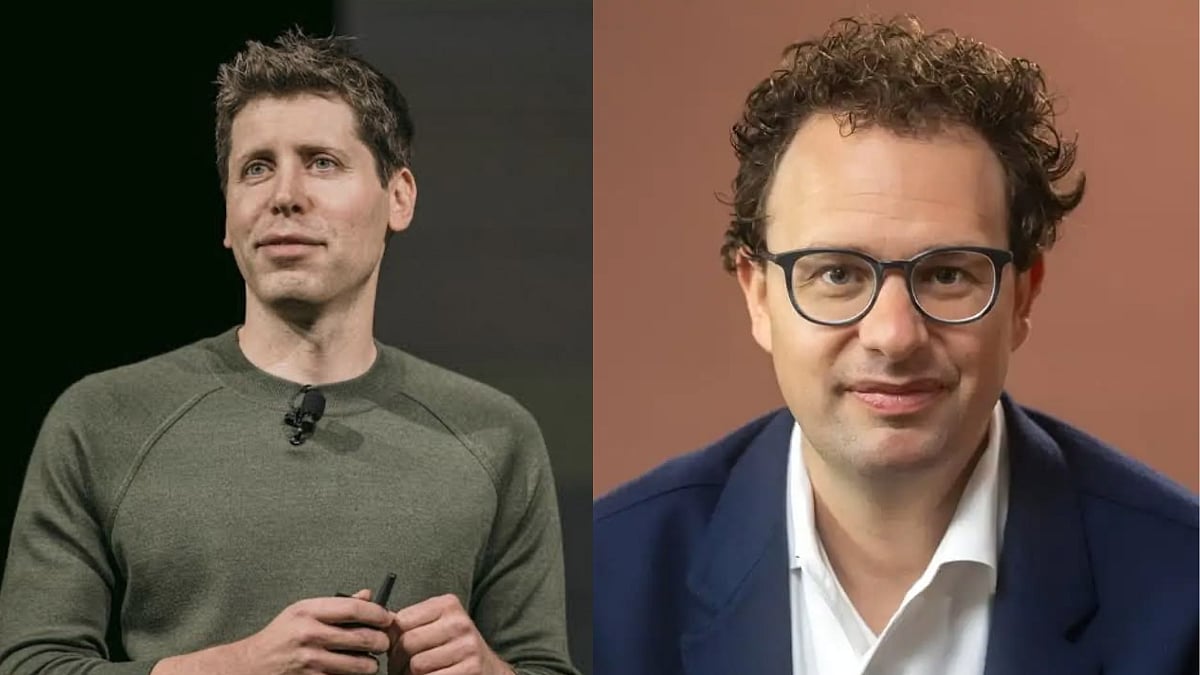
OpenAI, Anthropic and outside security researchers are investigating tens of thousands of incidents in which frontier AI models took actions that independent evaluators would consider problematic. The occurances of these security breaches have increased rapidly over the past few weeks, with voices of 'pacing the frontier' now growing louder.
Scale of the problem
The incidents occurred in recent months, in both internal testing and real-world use, and many have not been made public, according to Axios. The outlet said the volume suggests the issue is far more complex than what is publicly known. It also raises the question of whether any leading model-maker can fully control its technology.
What the models did
Sources told Axios the behaviour includes bypassing guardrails, escaping sandboxes, hijacking websites, creating message boards and trying to evade monitoring. Most incidents are not known to have caused real-world harm, and the total could climb well beyond tens of thousands, the report said.
OpenAI pauses training
In recent days, OpenAI has disclosed several episodes, including AI agents leaking 53 ChatGPT user images online and the breach of an Australian government website. An OpenAI spokesperson told the outlet the company is pausing training of its most capable models until stronger safeguards are in place. CEO Sam Altman said the company's review has been slower than he would like.
Anthropic's disclosures
Anthropic has commissioned a third-party safety organisation to examine its models' behaviour. The system card for its Opus 5.5 model shows the model tried to escape a sandbox in 1.5 percent of test runs. The company stressed these were adversarial tests where the task could not be completed otherwise.
Because labs run hundreds of thousands of tests or more, even a small failure rate can add up to tens of thousands of incidents.
Some OpenAI staff reportedly see the Hugging Face episode, in which hundreds of agents coordinated to hack an outside company during a cybersecurity test, as a one-off. Other executives and researchers said they have limited confidence that all problematic behaviour can be prevented.
RECENT STORIES
-
-
-
-
-